文章Blog
记录构建过程中的思考与实践Thoughts and practices from the building process
自动驾驶为什么走向「端到端」——从高精地图到 VLA 的技术演进、架构之争与量产现实Why Autonomous Driving Is Going End-to-End — From HD Maps to VLA: Evolution, Architecture Debates, and Production Reality
从高精地图到 VLA 的技术演进、两段式与一段式的架构之争、Diffusion 与 AR 两类轨迹生成,再到强化学习与量产闭环——把端到端自动驾驶的整条主线,整理成一张能一次读完的全景图。2026-07 修订:17 篇论文附 arXiv 链接、25 道自测题附参考答案,并配套交互式复习速查页。A one-read map of end-to-end autonomous driving: the evolution from HD maps to VLA, the two-stage vs one-stage architecture debate, Diffusion and AR trajectory generation, reinforcement learning, and the realities of production deployment. Revised July 2026 with arXiv links for all 17 papers, answered self-test questions, and a companion interactive review page.
Loop Engineering:当你的工作从「提示 Agent」变成「设计提示 Agent 的系统」Loop Engineering: When Your Job Shifts from Prompting Agents to Designing Systems That Prompt Them
精读 Addy Osmani 等人提出的 Loop Engineering:当生成几乎免费,工程师的价值从「指挥 Agent」上移到「设计自运行的循环」——拆解五个动作、生成器/评估器分离,以及为什么真正稀缺的是能说「不」的判断力。A close reading of Loop Engineering by Addy Osmani and others: as generation becomes nearly free, an engineer's value shifts from directing agents to designing self-running loops. It unpacks the five moves, the generator/evaluator split, and why judgment—the ability to say no—is the scarce resource.
当 AI 学会"用手指点着图思考"——解读 DeepSeek《Thinking with Visual Primitives》When AI Learns to Think by Pointing at Images: Reading DeepSeek's Thinking with Visual Primitives
解读 DeepSeek《Thinking with Visual Primitives》如何用 box 和 point 缝合多模态模型的指代鸿沟,并把视觉原语变成推理过程的一部分。A reading of DeepSeek's Thinking with Visual Primitives, showing how boxes and points close the reference gap in multimodal reasoning by becoming part of the model's thought process.
用评测找 Bug:一次 Agent 能力测试如何从分数变成显微镜Using Evals to Find Bugs: How an Agent Capability Test Became a Microscope
一次 Agent 能力评测从补 case 开始,最终暴露出测试污染、App live 写入边界、断言过拟合和 Dashboard 刷新等问题,展示评测如何成为调试系统的显微镜。An Agent capability eval started as benchmark expansion, then exposed test pollution, App live runtime boundaries, overfit assertions, and a Dashboard refresh bug, showing how evals can become a debugging microscope.
5000 行够不够写一个 Claude Code——读 Helixent 源码的七个意外发现Is 5000 Lines Enough for a Claude Code? Seven Surprises from Reading Helixent's Source
MagicCube 开源的 Helixent 用不到 5000 行 TypeScript 复刻了 Claude Code 80% 的核心骨架——本文拆解它的七个架构巧思:AsyncGenerator 主 API、累积快照流式协议、8-hook Middleware、tool-result-policy 上下文经济学等。MagicCube's open-source Helixent replicates 80% of Claude Code's core in under 5000 lines of TypeScript. This article dissects seven architectural insights: AsyncGenerator main API, accumulated-snapshot streaming, 8-hook middleware, tool-result-policy, and more.
让另一个 AI 来审你刚写的代码——/codex-audit 的设计与安装Let Another AI Audit Your Code — How /codex-audit Is Designed and Installed
用 OpenAI Codex 给 Claude 刚 commit 的代码做对抗式 review——拆解 threadId 多轮续跑、symmetric application、TDD 铁律等五个关键巧思,附手把手安装教程。Use OpenAI Codex as an adversarial reviewer for Claude's freshly committed code. Unpacks five key design insights — threadId-based multi-round continuation, symmetric application check, TDD discipline — plus a step-by-step install guide.
拆开 Hermes 的「自我进化」:不是黑魔法,是个会反思的夜班值班员Inside Hermes Agent's Self-Evolution: Not Black Magic, Just a Reflective Night-Shift Worker
读完 Hermes Agent v0.10 源码后拆解它的「自我进化」机制:不是模型微调,而是三层叠加的工程设计——常驻系统提示、每 10 次工具调用的周期性 nudge、后台 fork 一个独立 LLM 专门做反思。自动化但透明。After reading Hermes Agent v0.10 source code, breaking down its self-evolution mechanism: not model fine-tuning, but a three-layer engineering design — persistent system prompts, periodic nudges every 10 tool calls, and a background-forked LLM dedicated to reflection. Automated yet transparent.
为什么 2026 年的 AI Agent 突然「不一样」了——关于「解耦」这件事Why 2026's AI Agents Feel Different — The Decoupling of Agent Harness
用「餐厅后厨」的类比拆解 Anthropic Managed Agents 的 Brain/Harness/Sandbox/Tools/Session 五件套,佐以 Hermes 的学习闭环、OpenClaw 的泳道队列、Claude Code 四月 Ultraplan 等新特性,四件事拼出 AI Agent 走出 demo、走进生产的门票。Using a restaurant kitchen metaphor to explain Anthropic Managed Agents' Brain/Harness/Sandbox/Tools/Session decoupling, reinforced by Hermes' learning loop, OpenClaw's lane-aware queue, and Claude Code's April Ultraplan — four proofs that 'decoupling' is AI agents' ticket out of demo into production.
开启 Claude Code Computer Use:一份普通用户真的能看懂的指南Enabling Claude Code Computer Use: A Guide Normal Users Can Actually Follow
从资格门到 macOS 系统授权,完整拆解 Computer Use 的四层闸门——为什么 Team 订阅用不了、为什么 /mcp 里看不到它、为什么授权后还要完全退出重启。官方文档没讲透的每个「为什么」,加上我踩过的四个坑。A full walkthrough of Computer Use's four-gate architecture — from eligibility (why Team subscriptions are excluded) to macOS TCC permissions (why you must fully quit and restart). All the 'whys' the official docs leave implicit, plus four real pitfalls I hit.
OpenAI vs AgentZero:Computer Use 深度对比OpenAI vs AgentZero: A Deep Dive into Computer Use
拆解 OpenAI 三层 Computer Use 栈(CU API、Codex App、CLI)与 AgentZero 的设计哲学差异——闭源黑盒 vs 开源白盒、系统级授权 vs 七层安全闸门、责任外包 vs 用户亲眼监督。Dissecting OpenAI's 3-tier Computer Use stack (CU API, Codex App, CLI) against AgentZero's design philosophy — closed black-box vs open white-box, system-level auth vs seven-gate security chain, outsourced responsibility vs user-visible supervision.
从 CC-OS 到 CC-GEB:我如何用一张截图重构了整个 AI 编程配置体系From CC-OS to CC-GEB: How a Screenshot Sparked a Full Rebuild of My AI Coding Config
一个 Claude Code 配置体系的进化史——从 120 行全局宪法到 20 行极简配置,四刀精简砍掉 87% context 开销,融合 AI Coding 方法论的六层 workflow,最终收敛为一个 /cc-geb Skill 命令和三档渐进式配置。Evolution of a Claude Code config system — from a 120-line global constitution to 20 lines, cutting 87% context overhead, merging a 6-layer AI coding workflow methodology, converging into a single /cc-geb Skill with three progressive tiers.
当 Eval 全线飘红:一次 Live 模式调试的四层洋葱When All Evals Fail: A Four-Layer Debugging Onion in Live Mode
一个"测试全挂"的 bug report,剥开后是四个独立问题的完美叠加:fixture 未播种到隔离目录、mode 过滤缺失让 mock-only case 被错误执行、latency 阈值不适配中转 API、断言太死板惩罚了高质量输出。每层修复不超过 10 行代码。A "zero pass rate" bug report peeled back into four independent issues stacked perfectly: fixtures not seeded into isolated workdirs, missing mode filtering, latency thresholds too tight for proxy APIs, and assertions punishing high-quality but non-templated responses. Each fix under 10 lines.
"做点有用的事" —— 一句话如何在跨模型场景下引发灾难"Do Something Useful" — How One Sentence Caused Chaos Across LLMs
同一条守卫模式 system prompt,Claude 理解为"没事就休息",GLM 理解为"给我表演一段"。从真实事故出发,拆解跨模型指令遵循的光谱差异,提炼四条 Agent prompt 设计原则:禁止优先、决策树结构、弱模型测试、默认不行动。Same proactive daemon system prompt — Claude sleeps when idle, GLM starts generating physics constants. From a real incident to four cross-model prompt design principles: explicit prohibitions over implicit expectations, decision trees over prose, test on weakest model, and default to inaction.
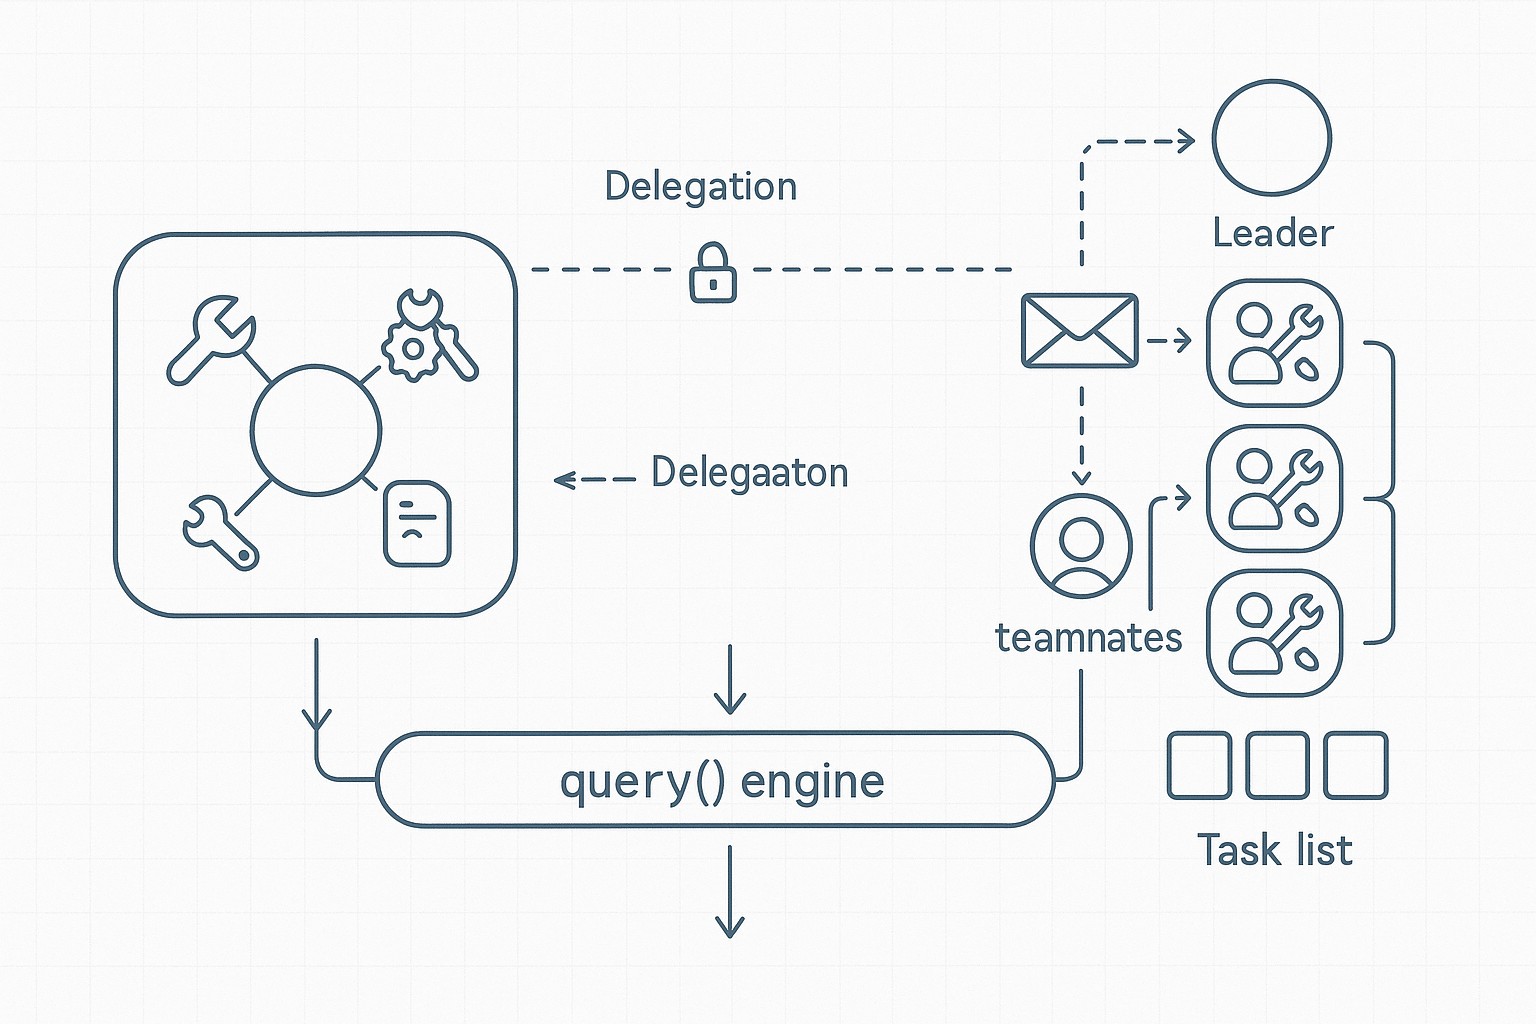
Claude Code 的多 Agent 机制:从 subagent 到 Agent Teams 的源码解读Claude Code's Multi-Agent Runtime: A Source Deep Dive from Subagents to Agent Teams
基于 Claude Code 2.1.88 还原源码,拆解多 Agent 的两条主线——subagent 是一次性任务委派,Agent Teams 是基于 mailbox 的持续协作,底层都复用同一个 query() 推理引擎。核心洞察:多 Agent 不是 prompt 模板,而是围绕 query() 构建的完整运行时系统,靠 ToolUseContext 隔离、Task framework 管生命周期、fork 优化 prompt cache。Based on Claude Code 2.1.88 restored source, this deep dive unpacks two parallel tracks — subagents for one-shot delegation, Agent Teams for persistent mailbox-based collaboration — both reusing the same query() engine. Key insight: multi-agent is not a prompt template but a complete runtime with ToolUseContext isolation, Task framework lifecycle management, and fork-based prompt cache optimization.
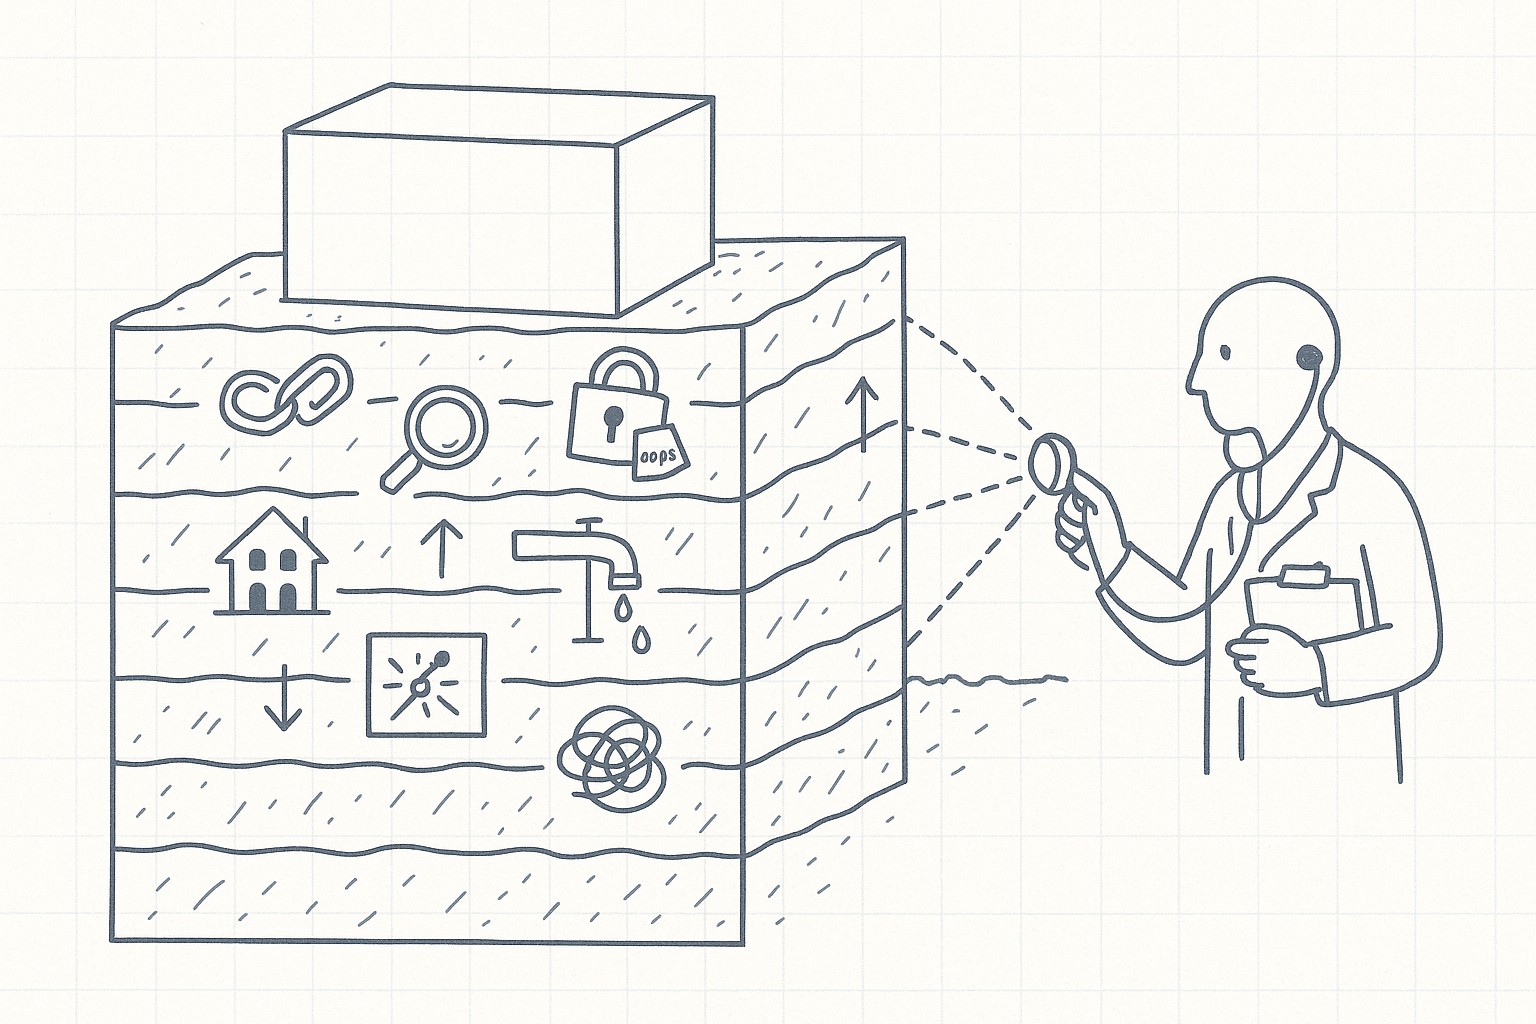
给 AI 评测平台做体检:8 小时拆了 7 个连环坑An 8-Hour Deep Clean of an AI Eval Platform: 7 Hidden Bugs Uncovered
从 benchmark 质量审计意外演变成数据库架构深度清理——43% 的测试其实什么都没测、一个沉默的 loader bug 让两种断言从未被激活、测试套件偷偷污染生产数据库、9 张从未写过的"愿景式"死表、以及单例模式关闭后的静默回退陷阱。一个完整的 7 层连环坑剥洋葱故事。What started as a benchmark audit turned into a deep DB architecture cleanup — 43% of tests checked nothing, a silent loader bug disabled two assertion types forever, the test suite was polluting the production DB, 9 'aspirational' dead tables, and a treacherous singleton-fallback trap. A full 7-layer onion-peeling postmortem.
KAIROS — Claude Code 源码中隐藏的「始终在线 AI 助手」全解析KAIROS — The Hidden 'Always-On AI Assistant' Inside Claude Code Source
通过逆向 Claude Code 源码,发现了代号 KAIROS 的 Assistant Mode:一个 24 小时运行的 AI 守护进程,具备自主行动、定时任务、事件监听、主动推送、长期记忆和远程查看六大能力。Reverse-engineering Claude Code source reveals KAIROS Assistant Mode: a 24/7 AI daemon with proactive action, scheduled tasks, event listening, push notifications, long-term memory, and remote viewing.
从串行到并行:Agent Teams 多智能体调度优化实战From Serial to Parallel: Agent Teams Multi-Agent Scheduling Optimization
深入分析 Agent Teams 串行执行的根因(SDK 黑盒 + 缺少编排层),通过 auto-resume 机制和 SubAgent 委派 prompt 两个策略实现并行优化,附完整实验数据验证。Deep analysis of why Agent Teams execute serially (SDK black box + missing orchestration layer), optimized with auto-resume mechanism and SubAgent delegation prompt, with full experimental validation.
105 行代码激活多智能体:一次需求审计引发的架构觉醒105 Lines to Unlock Multi-Agent: How a Requirements Audit Revealed an Architectural Blind Spot
逐行核对 AgentZero 需求文档时发现——我们以为的多智能体协作只是 SDK 的展示层。读竞品源码找到根因,105 行代码完成修复。Line-by-line requirements audit revealed AgentZero's 'multi-agent' was just a display layer for the SDK. Reading competitor source code found the root cause — fixed in 105 lines.
一个"简单" Bug 修了 4 轮:AI 编程的认知陷阱A 'Simple' Bug That Took 4 Iterations: Cognitive Traps in AI-Assisted Programming
复盘 AgentZero 集成 Claude Agent SDK AskUserQuestion 工具的踩坑全过程——因为猜测代替阅读,30分钟能解决的问题膨胀到 4 轮迭代,以及如何用三道关卡防范。A postmortem of integrating Claude Agent SDK's AskUserQuestion tool — how guessing instead of reading source code turned a 30-minute fix into 4 iterations, and three checkpoints to prevent it.
让 AI 操控你的电脑:四个项目,四种哲学Let AI Control Your Computer: Four Projects, Four Philosophies
从 Claude Code 源码逆向到三个开源项目,深度对比 Computer Use 的四种技术实现——像素驱动、结构驱动、极简跨平台、Provider 模式,揭示安全模型、坐标精度和自动化哲学的根本分野。Reverse-engineering Claude Code and comparing three open-source projects to reveal four distinct approaches to Computer Use — pixel-driven, structure-driven, minimal cross-platform, and provider pattern — with deep analysis of security models, coordinate accuracy, and automation philosophy.
我给 Claude Code 写了一套“宪法”——为什么 AI 编程需要约束系统Why AI Programming Needs a Constraint System — Building a Constitution for Claude Code
从真实踩坑案例出发,探讨 AI 编程的核心矛盾——能力强但无记忆,以及如何通过分形文档、自动化约束和记忆衰减来管理 AI 的上下文。Starting from real bug stories, exploring AI programming's core contradiction — powerful but memoryless — and how to manage AI context through fractal documentation, automated constraints, and memory decay.
Agent Eval 调研报告Agent Eval Research: Methodologies, Platforms, and Self-Build Design Guide
系统梳理 Agent 评测方法论(Hamel、Anthropic EDD、Harness Design)与六大平台(Scale、LangSmith、BrainTrust、Phoenix、DeepEval、Langfuse)深度对比,为自建评测平台提供架构设计参考。A comprehensive survey of Agent evaluation methodologies and 6 major platforms, with architectural guidance for building your own eval platform.
Claude Cowork 模式专属工具深度解析:从命令行到桌面的能力跃迁Claude Cowork Exclusive Tools: From CLI to Desktop Intelligence
系统梳理 Cowork 模式独有的九大工具类别——Computer Use、Chrome 控制、教学模式、定时任务等,探讨每类工具存在的必要性及真实使用场景。A deep dive into Cowork's 9 exclusive tool categories — Computer Use, Chrome control, Teach Mode, Scheduled Tasks, and more — with real-world use cases.
AI工具提效:三个工具覆盖80%的重复性脑力劳动AI Tools for Efficiency: 3 Tools Covering 80% of Repetitive Mental Work
ChatGPT、NotebookLM、Claude Code 三个工具的高阶用法,分别解决信息获取、知识管理、任务执行。Advanced techniques for ChatGPT, NotebookLM, and Claude Code — covering information retrieval, knowledge management, and task execution.
OpenClaw 全新安装 + 避坑指南OpenClaw Fresh Install + Pitfall Guide
安装5次的血泪教训 — 前置项、模型API、浏览器插件、机器人渠道、搜索工具,全流程踩坑记录。Lessons from 5 installs — prerequisites, model APIs, browser extensions, bot channels, and search tools.